Step-by-Step Teaching Guide
Step 1: Understanding the Problem First (The "Why")
Before learning the technology, understand what problem it solves.
The Shift in AI Workloads
OLD AI WORLD                    NEW AI WORLD
─────────────────               ─────────────────
Training models                 Running/serving models
One big task                    Many chained tasks
Short responses                 Long reasoning chains
Single AI system                Multiple AI agents collaborating
What is Agentic AI?
Think of agentic AI like a team of workers rather than one person:
- Each AI agent reasons, uses tools, accesses data, and talks to other agents
- They generate responses one token at a time
- They maintain large context windows (up to 100,000 tokens)
- Small delays multiply across complex chains of work
Real-world analogy: Imagine a relay race where each runner must wait for the previous one. If each handoff takes even 1 second longer, a 10-person relay loses 10 seconds total. Agentic AI has the same problem — called decode latency.
Why This Matters for Infrastructure
| Demand | Traditional Infrastructure | Agentic AI Requirement |
|---|---|---|
| Token speed | Moderate | Ultrafast (3,400 tokens/sec) |
| Context size | Small | 100,000+ tokens |
| Latency tolerance | Flexible | Near-zero |
| Scale | Single model | Multi-agent, multi-system |
Step 2: The Core Concept — "Extreme Codesign"
What Does Codesign Mean?
Codesign means designing multiple components together as one system, rather than building each part separately and connecting them later.
TRADITIONAL APPROACH:
[Chip A] → [Network B] → [Software C]
(Each optimized separately, gaps between them)

EXTREME CODESIGN APPROACH:
[Chip A + Network B + Software C]
(All designed together, no gaps)
Analogy: A car engine, transmission, and wheels designed by three separate companies vs. a Formula 1 car where every part is engineered as one unified system for maximum performance.
Why "Extreme" Codesign?
The word "extreme" signals that NVIDIA is applying this principle at every single layer:
- Silicon chip design
- Rack-scale hardware
- Networking switches
- Software stack
- Infrastructure services
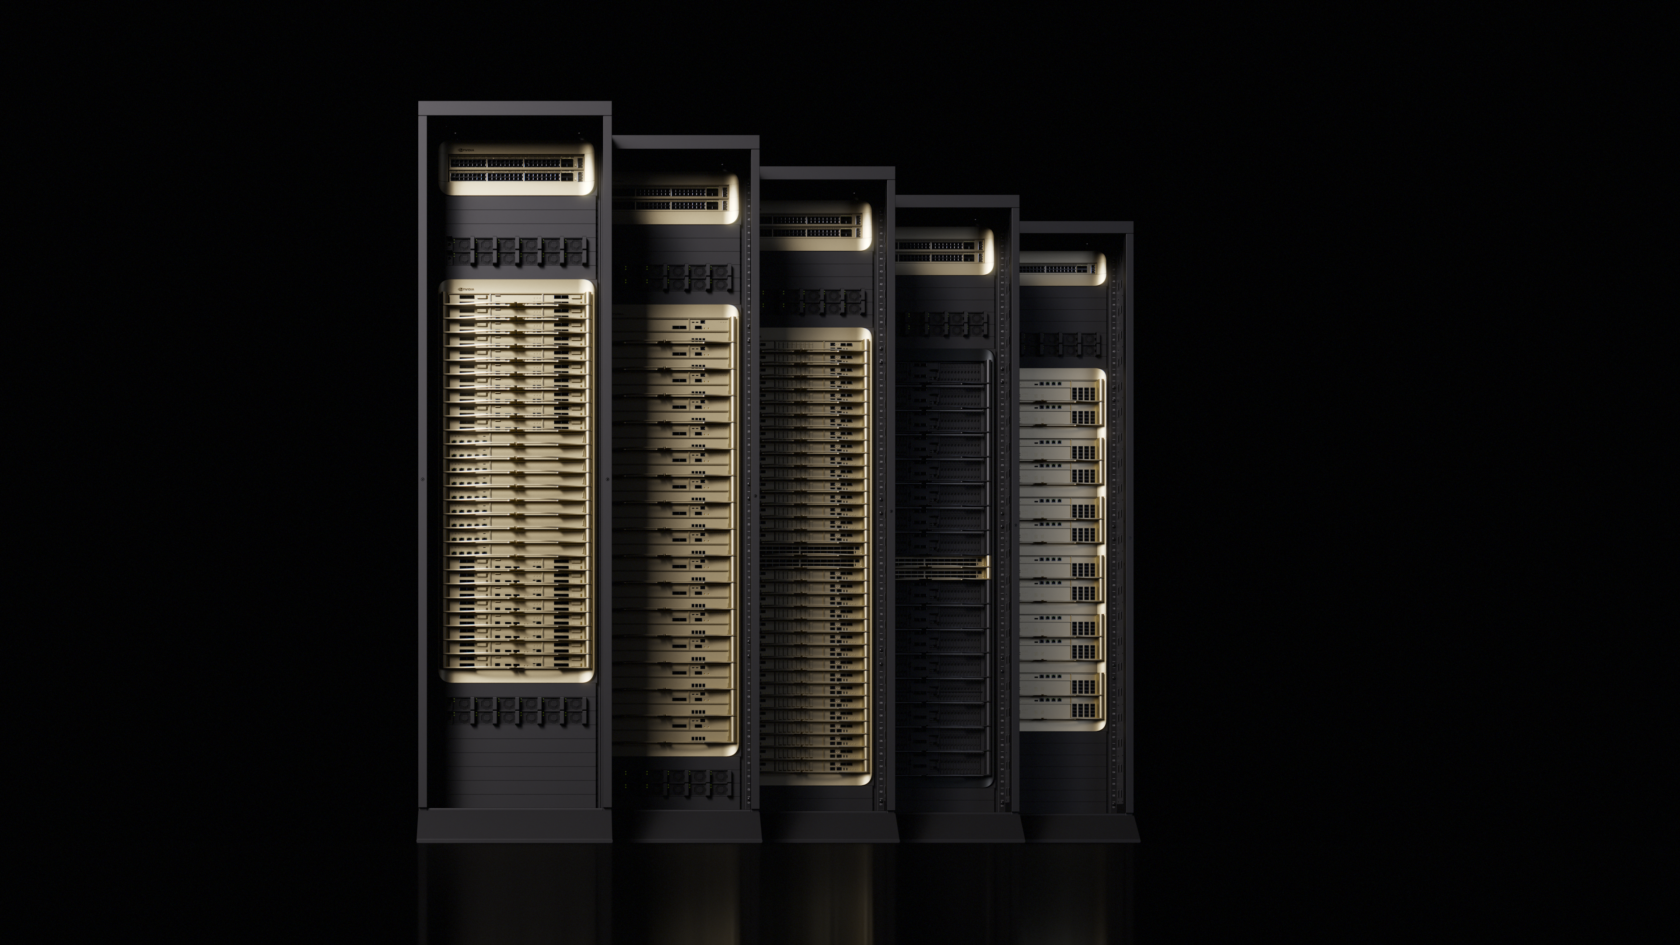
Step 3: The AI Factory Architecture — Layer by Layer
Think of an AI factory like a physical manufacturing plant, but for producing tokens (AI outputs) instead of physical goods.
┌─────────────────────────────────────────────┐
│              AI FACTORY                      │
│                                             │
│  [Raw Input/Context]                        │
│         ↓                                   │
│  [Vera Rubin NVL72 — Context Processing]    │
│         ↓                                   │
│  [Groq 3 LPX — Token Generation]           │
│         ↓                                   │
│  [Spectrum-X — Moving Data Between Racks]   │
│         ↓                                   │
│  [Scale-In — Security, Storage, Management] │
│         ↓                                   │
│  [Output: Tokens/Intelligence]              │
└─────────────────────────────────────────────┘
Layer 1: Vera Rubin NVL72 — The Core Compute Platform
What it is: A rack-scale GPU system (NVL72 = 72 GPUs in one rack)
What it does:
- Handles large-scale context processing (reading and understanding long inputs)
- Acts as the "brain" for complex reasoning
- Provides the foundation everything else connects to
Key metric: Benchmark shows 3,400 output tokens/second on 100,000-token contexts — 4x faster than nearest competitor
Layer 2: NVIDIA Groq 3 LPX — The Token Generation Accelerator
This is the most technically novel component. Let's break it down carefully.
What is an LPU?
| Component | Full Name | Primary Job |
|---|---|---|
| GPU | Graphics Processing Unit | Parallel computation, context processing |
| LPU | Language Processing Unit | Fast, deterministic token generation |
The GPU + LPU Partnership
RUBIN GPU                    GROQ 3 LPX (LPU)
─────────────                ────────────────
Processes context            Generates tokens
Handles complexity           Handles speed
Large-scale compute          Low-latency decode
"Understanding"              "Speaking"
Analogy: Think of a GPS navigation system. The GPU is like the map database and route calculation engine (complex, powerful). The LPU is like the voice output system (must respond instantly, predictably, every time you need a direction).
Why Decode Latency is the New Problem
Agent Task Chain:
[Agent 1 thinks] → [generates tokens] → [Agent 2 reads] → [Agent 2 thinks] → ...

If each token generation step takes 10ms too long:
10ms × 1,000 tokens × 5 agents = 50 SECONDS of added delay
Groq 3 LPX solves this by:
- Specializing in latency-sensitive decode workloads
- Using 256 LP30 accelerators connected via direct chip-to-chip links
- Operating as a "giant processor" for deterministic inference
- Eliminating the traditional speed vs. throughput tradeoff
Layer 3: Spectrum-X Multiplane — The Network
The problem it solves: As AI factories grow, connecting thousands of GPUs requires bigger networks. Traditional scaling adds a third network tier, which causes:
- More latency
- Unpredictable slowdowns
- Higher costs (cabling, optics, power)
How Multiplane Works
TRADITIONAL SCALING:
Tier 1 → Tier 2 → Tier 3 (new tier added)
         ↑ Latency increases here

SPECTRUM-X MULTIPLANE:
Plane 1 ─┐
Plane 2 ─┤→ [ConnectX SuperNIC manages all planes]→ Application sees ONE fast connection
Plane 3 ─┘
(Still only 2 tiers, but scales to 512,000 GPUs)
Key Performance Numbers
| Metric | Value |
|---|---|
| Max GPU scale | 512,000 GPUs |
| Performance vs. standard Ethernet | 1.6x better |
| Bandwidth retained if one plane fails | ~90% |
| Hardware recovery speed vs. software | 11x faster |
| AI factory output improvement | 1.6x higher |
The ConnectX SuperNIC Role
The ConnectX SuperNIC acts like an intelligent traffic controller:
- Automatically splits traffic across planes
- Instantly reroutes around failures
- Applications see one seamless connection — no complexity exposed
Layer 4: Scale-In Infrastructure — The Fifth Pillar
What it is: A new category of accelerated infrastructure powered by BlueField-4 processors and DOCA software
What it does: Handles everything that supports AI compute without consuming GPU resources:
Scale-In Handles:
├── Multi-tenant networking (multiple users sharing infrastructure)
├── High-performance storage access
├── In-silicon security (security built into the chip)
├── Elastic provisioning (scaling resources up/down)
└── Real-time observability (monitoring what's happening)
Analogy: If the AI factory is a hospital, the GPUs are the surgeons. Scale-In is the entire hospital administration — scheduling, security, supply chain, records — that keeps surgeons focused on surgery rather than paperwork.
Why it matters for agentic AI:
- Agents continuously interact with data, storage, and services
- Security must scale alongside compute
- Infrastructure services must be accelerated, not just software-defined
Layer 5: NVLink Fusion — Connecting Custom Silicon
The problem: Some companies (hyperscalers) build their own custom chips (XPUs). Previously, these couldn't easily connect to NVIDIA's ecosystem.
What NVLink Fusion does:
WITHOUT NVLink Fusion:
[Custom XPU] ←→ [NVIDIA GPU]
(Slow connection, separate ecosystems, duplicated infrastructure)

WITH NVLink Fusion:
[Custom XPU] ←NVLink→ [NVIDIA GPU]
(High-bandwidth, low-latency, shared rack/network/software)
Key benefit — Decoupling buildout from silicon readiness:
Traditional:
"We can't build the data center until our chip is ready"

With NVLink Fusion:
"Build the data center now with GPUs, swap in XPUs when ready"
(Share racks, networking, cooling, power, management)
Step 4: How It All Connects — The Complete Picture
Now let's see how all layers work together for one agentic AI task:
USER REQUEST: "Analyze this 100,000-token document and coordinate
               with 3 other AI agents to produce a report"

STEP 1: Request arrives
        → Scale-In handles security, routing, tenant isolation

STEP 2: Context processing
        → Vera Rubin NVL72 GPUs process the 100,000-token context
        → Spectrum-X Multiplane moves data between racks at full speed

STEP 3: Token generation begins
        → Groq 3 LPX LPUs generate response tokens at ultrafast speed
        → GPUs and LPUs jointly compute every model layer

STEP 4: Agent coordination
        → Multiple agents communicate via Spectrum-X network
        → Scale-In manages storage access for each agent's data needs

STEP 5: Output delivered
        → 3,400 tokens/second, low latency, at scale
        → Infrastructure fully utilized, economics optimized
Step 5: Industry Adoption — Real-World Validation
Understanding who is adopting what confirms the technology's real-world relevance:
| Partner | What They Adopted | Why It Matters |
|---|---|---|
| Nebius | First to adopt Groq 3 LPX | Proves production readiness for cloud providers |
| CoreWeave | Spectrum-X Multiplane in production | Validates large-scale network architecture |
| SpaceXAI | Vera CPUs for agentic AI | Extends platform from Earth to orbital satellites |
SpaceXAI Use Case — Why Vera CPUs?
Agentic AI requires significant CPU work that GPUs aren't optimized for:
CPU-Intensive Agentic Tasks:
├── Orchestration (managing agent workflows)
├── Tool use (calling APIs, databases)
├── Code execution (running generated code)
├── Data processing (transforming inputs/outputs)
└── Simulation (modeling environments)
Vera CPUs provide:
- Leading per-core performance
- Exceptional memory bandwidth
- Predictable performance under load (critical for agents)
Step 6: Conceptual Summary — The "Token Factory" Mental Model
The article introduces the "token factory" concept. Let's solidify this:
PHYSICAL FACTORY          TOKEN FACTORY (AI Factory)
─────────────────         ──────────────────────────
Raw materials      →      Input data/context
Assembly line      →      GPU + LPU inference pipeline
Quality control    →      Intelligence integrity
Shipping network   →      Spectrum-X networking
Factory management →      Scale-In infrastructure
Output: Products   →      Output: Tokens/Intelligence
Economics: Cost/unit →    Economics: Cost/token
Four simultaneous requirements of a token factory:
| Requirement | Technology That Delivers It |
|---|---|
| Performance | Vera Rubin NVL72 + Groq 3 LPX |
| Throughput | LPU fleet + GPU codesign |
| Intelligence integrity | Full-stack codesign |
| Economic efficiency | Shared infrastructure, high utilization |
Key Takeaways — What You Should Now Know
✅ Agentic AI creates new infrastructure demands: long contexts, chained reasoning, multi-agent collaboration, and decode latency sensitivity
✅ Extreme codesign means designing compute, networking, and software as one unified system — not optimizing components in isolation
✅ Groq 3 LPX solves decode latency by pairing LPUs with GPUs — GPUs handle context, LPUs handle fast token generation
✅ Spectrum-X Multiplane scales AI networks to 512,000 GPUs without adding a costly third network tier
✅ Scale-In accelerates infrastructure services (security, storage, networking) so GPUs stay focused on AI compute
✅ NVLink Fusion lets custom silicon connect to NVIDIA's ecosystem, decoupling data center buildout from chip availability
✅ The "token factory" mental model frames AI infrastructure as a production system optimized for cost-per-token at massive scale